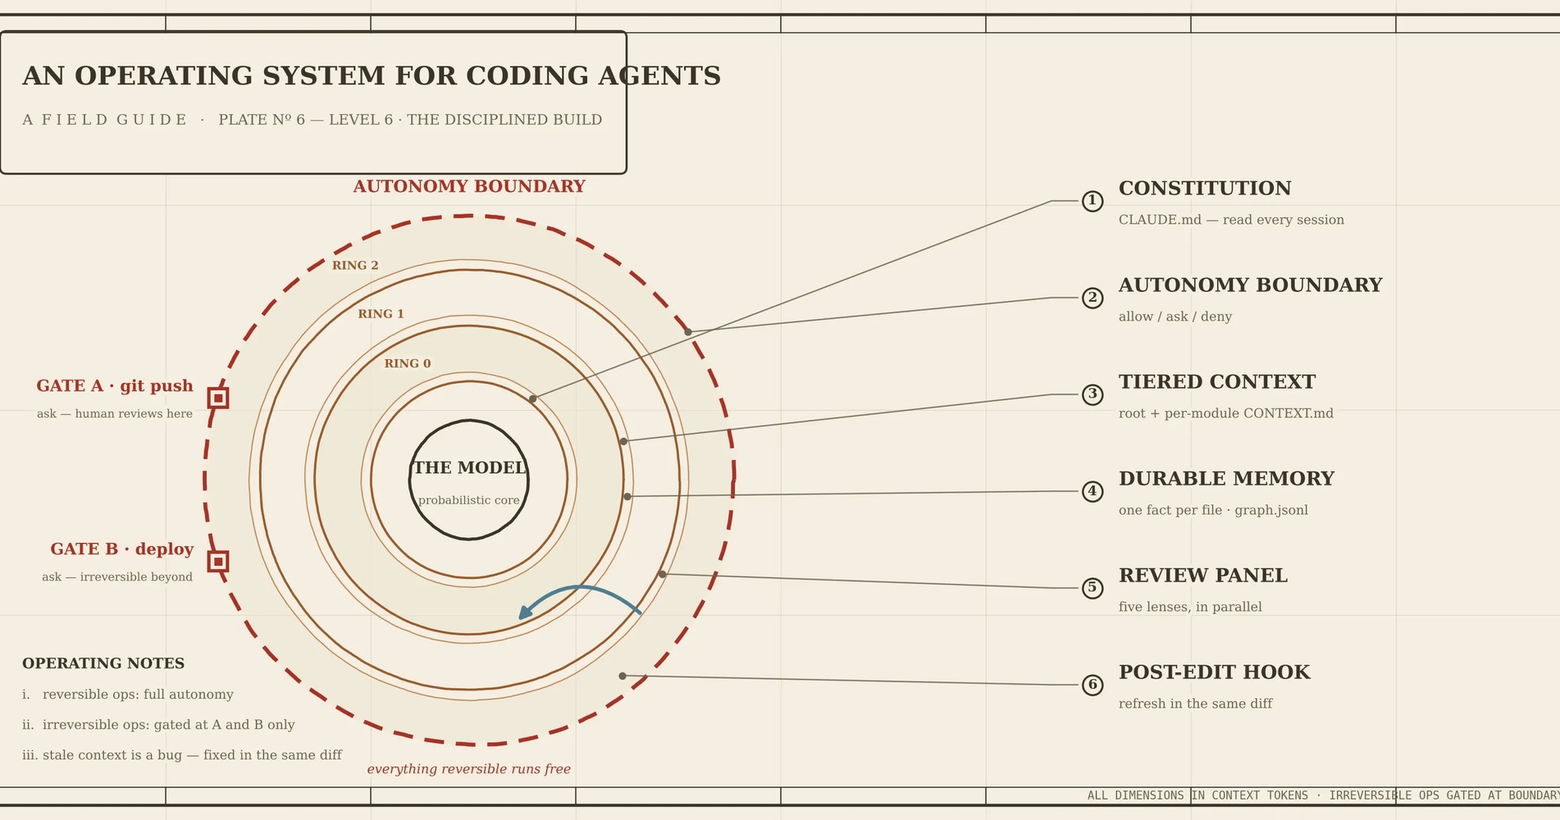
The first session with a coding agent is crisp: it reads the code, makes a clean change, writes a test. By the thirtieth, something has rotted — it re-discovers the same files, contradicts a decision it made three weeks ago, guesses the test command, and quietly stops writing tests because nobody made it. The fix isn’t a better model. It’s an operating system around the model: a constitution, an autonomy boundary, tiered context, durable memory, a review panel, and a post-edit hook.
Why the harness, not the model
A useful way to say it: the agent is the model plus its harness — the prompts, the tools, the context policies, the hooks, the sandboxes, the sub-agents, the observability wrapped around the raw model. The model is maybe a tenth of what decides whether you get working software over a quarter; the harness is the rest. The evidence is blunt. On the public Terminal-Bench 2.0 benchmark, LangChain moved a coding agent from outside the top 30 to the top 5 — a jump from 52.8% to 66.5%, or 13.7 points — by changing only the harness (system prompt, tools, and middleware like self-verification and loop detection), keeping the same model.
Examined honestly, most agent failures aren’t just model failures — they’re configuration failures: a missing tool, a vague rule, an absent guardrail, a context window stuffed with noise. So when quality decays across a long project, the lever is almost never “wait for a smarter model.” It’s the harness — and unlike the model, the harness is yours to build. The rest of this post is the concrete one.
The four things that decay (and the artifact that fixes each)
- Discipline — skips tests, expands scope → a constitution read every session
- Context — re-learns the repo → tiered
CONTEXT.md, maintained by a hook - Memory — repeats corrected mistakes → durable per-fact memory files
- Review — one blind spot applied uniformly → a multi-lens agent panel
1. A constitution (CLAUDE.md / AGENTS.md)
A lean, always-loaded file stating the non-negotiables: the workflow loop (Plan → Document → Implement → Test → Review → Commit), the autonomy boundary, the quality bars (tests in the same diff, no dead code, conventional commits), and adapter discipline (no vendor SDK in domain code). Keep it short — it’s read on every turn, so every line costs context budget.
2. An autonomy boundary, not a kill switch
The highest-leverage single decision: let the agent run free on everything reversible, pause only on the two things that aren’t — pushing to a remote and deploying. As a permissions config:
{
  "permissions": {
    "allow": ["Read","Edit","Write","Grep","Glob",
              "Bash(git add:*)","Bash(git commit:*)",
              "Bash(npm test:*)","Bash(npm run:*)","Bash(npm ci:*)","Bash(pytest:*)"],
    "ask":   ["Bash(git push:*)","Bash(npm publish:*)","Bash(aws:*)","Bash(terraform apply:*)","Bash(kubectl apply:*)"],
    "deny":  ["Bash(git push --force:*)","Bash(git push -f:*)","Bash(*--no-verify*)"]
  }
}
Now it works for an hour and commits a dozen times; you review at the push, not at every keystroke. The blast radius of “autonomous” stays bounded because the irreversible ops are the only gated ones. (Verify your runner’s match semantics — prefix vs substring differ — so --no-verify/--force denials and npm publish actually trip; broad globs like npm:* quietly allow npm publish.)
3. Tiered context the agent maintains
One giant context file rots and blows the budget. Tier it:
- Root
CONTEXT.md— the map: what this is, how to run/test, one-line module index, invariants, where state lives. Cap ~200 lines; the session-start read. - Per-module
CONTEXT.md— responsibility, key files, deps, gotchas, how to test just this module. Read before editing that module. DECISIONS.md— append-only: date, decision, why, alternatives rejected. (This one earns its own deep treatment once several agents share the repo — expanded in Part II.)
Rule: stale context is a bug, fixed in the same change that invalidated it — not “later.”
4. Durable memory + a tiny knowledge graph
Context describes the code; memory holds what the code can’t tell you across sessions — one fact per file, indexed:
memory/
  MEMORY.md                  # index: one line per fact
  user-prefers-X.md          # type: user | feedback | project | reference
  graph.jsonl                # {from, rel, to} — modules/decisions as nodes; depends-on/adapts/supersedes
The graph answers the question agents are worst at: “what breaks if I change this?”
5. A review panel, not a reviewer
Instead of one self-review, run focused sub-agents in parallel, each one lens, strict output:
product   — solves the stated problem? scope creep?   (plan stage)
architect — correctness, data model, failure modes, coupling
infra     — resource limits, deploy/rollback, resilience
security  — authz, input validation, secrets, audit trail
test-eng  — is the suite real, or happy-path theater?  (per change)
→ each returns: [BLOCKER|MAJOR|MINOR] (confidence%) — file:line — issue — fix ; VERDICT
Only high-confidence BLOCKER/MAJOR gate. Diverse lenses catch what a single pass misses; the confidence threshold keeps it from drowning you in nits. (Note: these are parallel agents reviewing one change — distinct from parallel agents making changes, which is Part II’s whole problem.)
6. A post-edit hook so nothing drifts silently
The piece that ties it together — fires after every edit and emits a checklist (a PostToolUse hook):
Wire it in settings.json, pointed at a tiny script:
{ "hooks": { "PostToolUse": [
  { "matcher": "Edit|Write|MultiEdit",
    "hooks": [ { "type": "command", "command": "python3 .claude/hooks/post-edit.py" } ] } ] } }
# .claude/hooks/post-edit.py — reads the tool event on stdin, emits a checklist as context
import json, sys
ev = json.load(sys.stdin)
path = ev.get("tool_input", {}).get("file_path", "the edited file")
checklist = (f"Post-edit refresh for {path}: (1) update the nearest CONTEXT.md if responsibility/"
"key-files/gotchas changed; (2) append a memory/graph edge on a dep/API change; "
"(3) log a DECISIONS.md line on a precedent; (4) update memory on a durable fact. "
"Make these edits in THIS change — stale context is a bug.")
print(json.dumps({"hookSpecificOutput": {"hookEventName": "PostToolUse", "additionalContext": checklist}}))It emits a checklist; the agent makes the edits in the same diff — reviewable, not a silent rewrite. It’s a reminder, not a silent rewriter — you always see what it changed.
The loop, in one line
session start: read root CONTEXT.md + MEMORY.md
per task:      plan → panel reviews plan → you approve →
               implement subtask (tests in same diff) → panel reviews diff →
               full test+lint → commit → hook refreshes context/memory/graph → next
only stops:    push and deploy
That’s the whole harness for one agent: six artifacts and a loop. Each is a few lines of config or a markdown file; together they’re the difference between an agent that’s brilliant for an afternoon and one that’s still trustworthy on the thousandth edit.
Part II — From one agent to a fleet
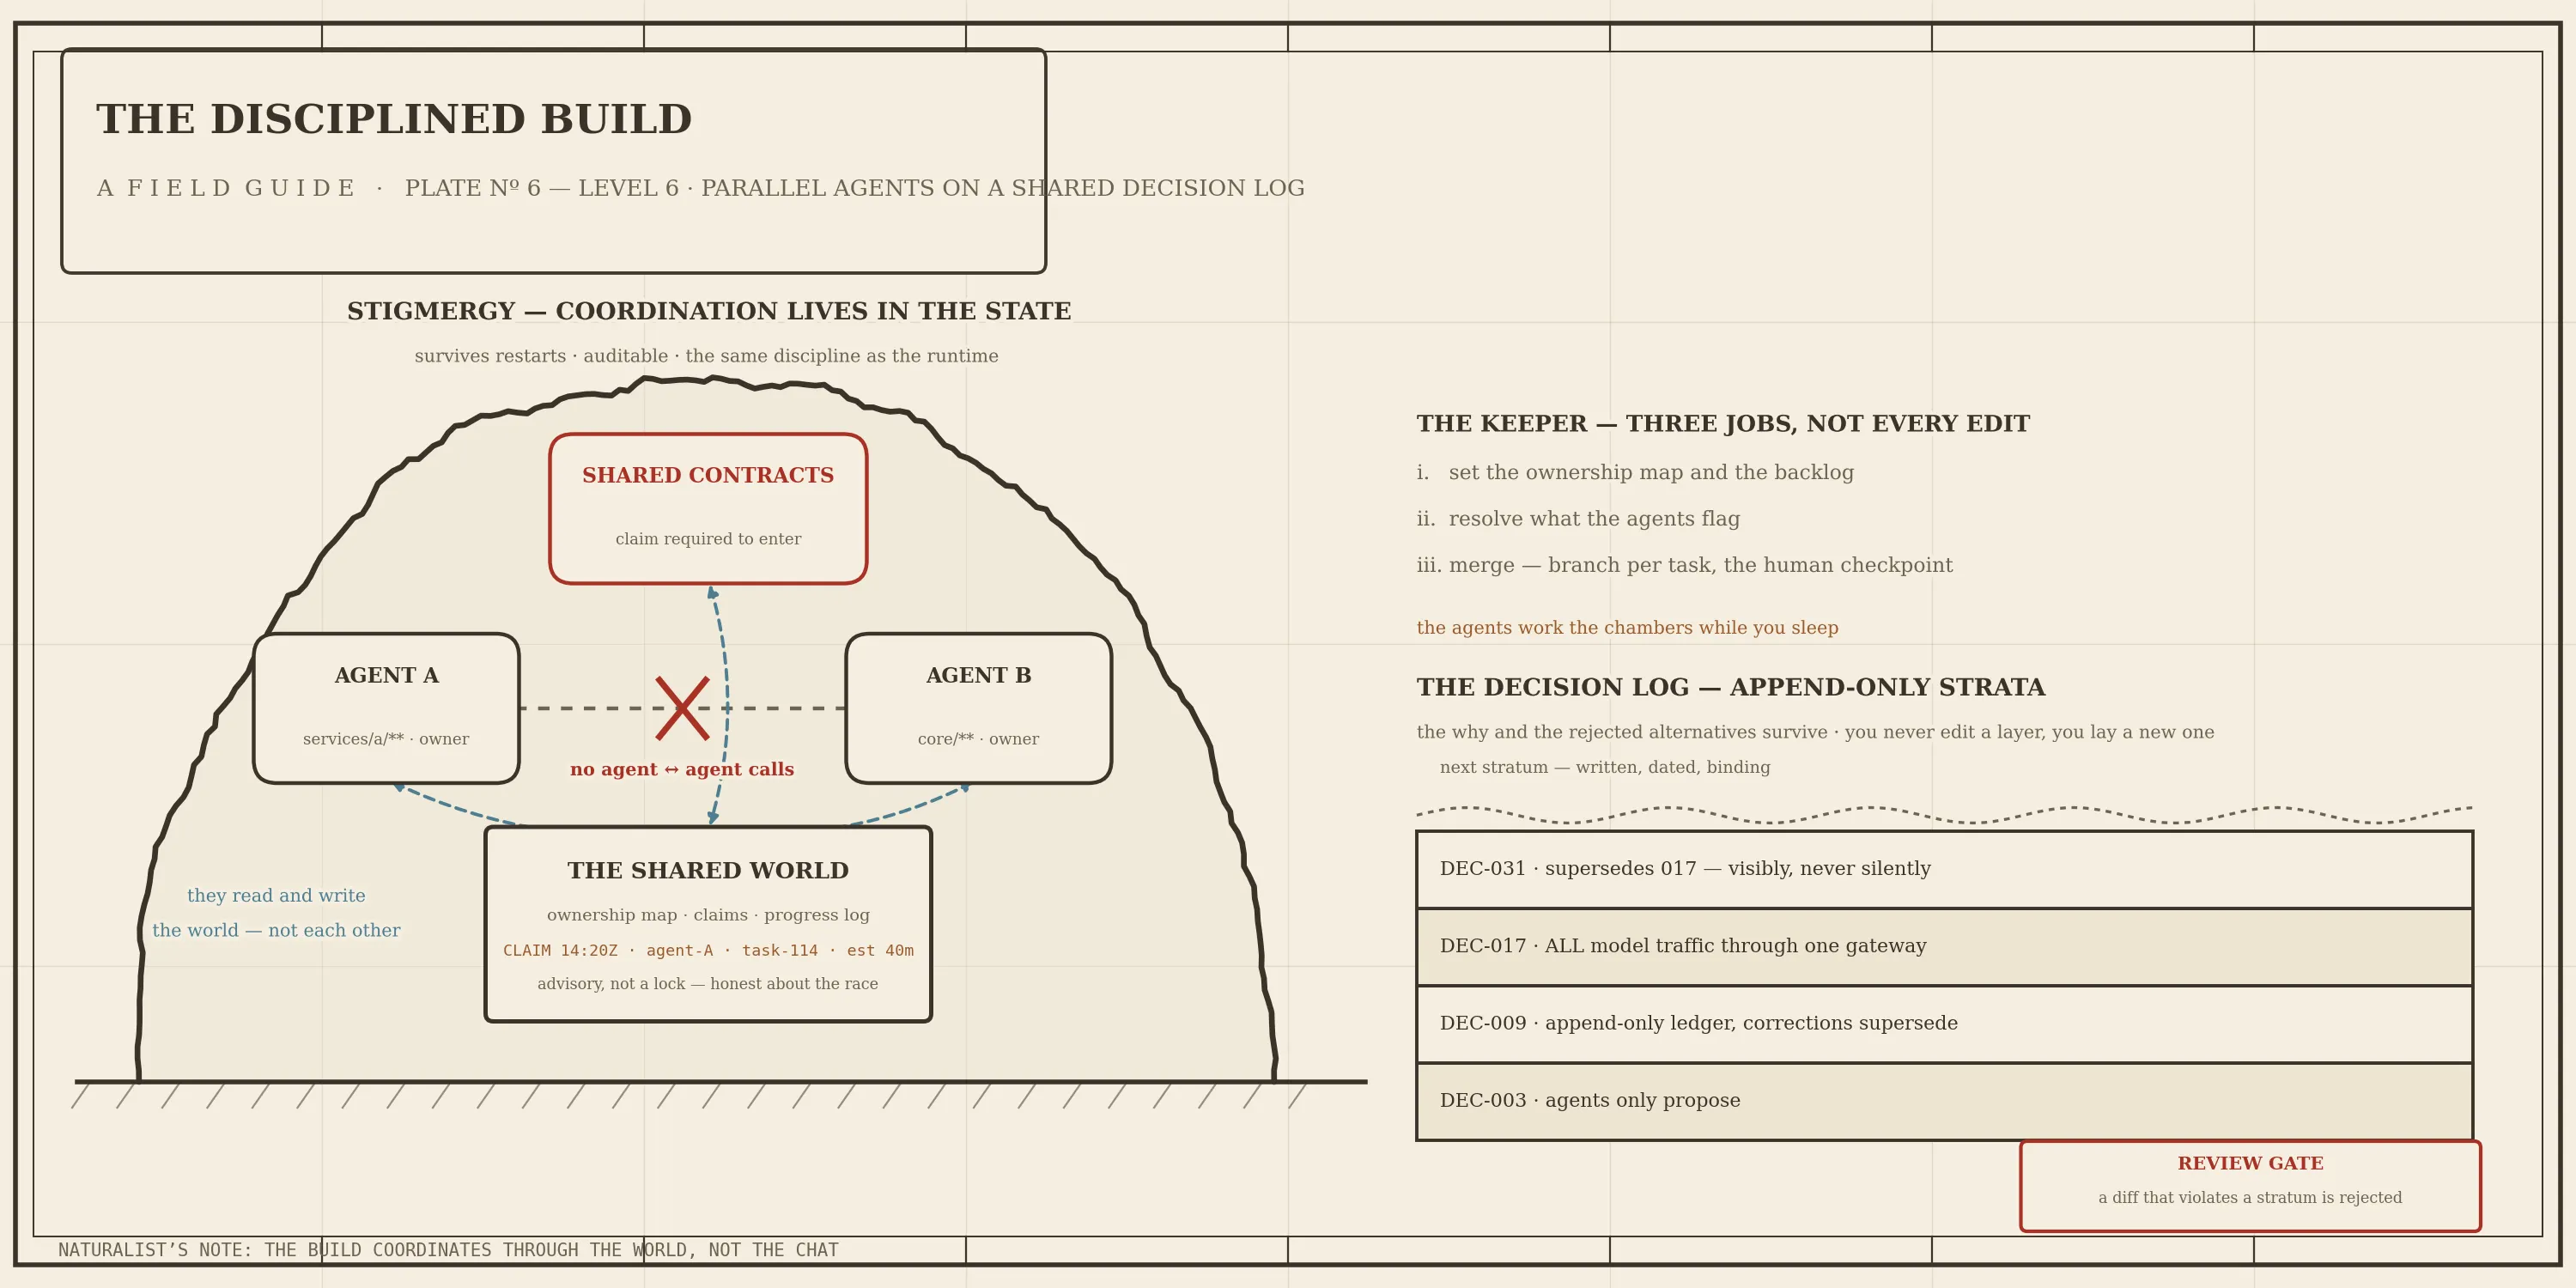
One agent, harnessed like this, stays productive for months. Now run several on the same repo at once — and a new failure mode appears that none of the artifacts above address: the agents collide. They edit the same files, undo each other’s work, and re-litigate a decision one of them already made. The instinct is to have them “communicate.” That doesn’t scale and isn’t reliable. What works is exactly what lets human teams parallelize: coordinate through shared, written state, not conversation — and write down the hard-won decisions so nobody, carbon or silicon, silently reverses them.
7. Coordinate through state, not chat (stigmergy)
Agents shouldn’t message each other. They read and write a small set of shared files that encode the state of the work — who owns what, what’s decided, what’s claimed, what’s done. Each agent acts on the world (the repo plus these files); the next one reads the world to decide what to do. Coordination becomes a property of the shared state, not of a conversation — which means it survives a restart and is auditable. Insects coordinate huge builds this way, by changing and reading a shared environment rather than talking. The same trick works here.
Ownership map — who owns which paths. Default ownership by directory; editing outside your area needs a claim.
| path                  | owner    | notes                       |
| core/**               | agent-B  | agent-A reads, doesn't edit |
| services/service-a/** | agent-A  |                             |
| shared/contracts/**   | shared   | claim required to change    |
Claim / release — cheap mutual exclusion, no lock server:
## CLAIM 2026-06-10T14:20Z · agent-A · task-114 · services/service-a/**
working: add retry to the fetch step    est: 40m
## RELEASE 2026-06-10T14:58Z · agent-A · task-114 · commit a1b2c3d
Rule: before claiming, scan for an open CLAIM on overlapping paths in the last few hours; if found, pick different work. Be honest that this is advisory/optimistic, not a lock — two agents can both scan, both see nothing, and both claim the same path (a TOCTOU race). If you need real mutual exclusion, use a primitive with atomic check-and-set: a uniquely-named git branch (the push fails if it already exists), or a conditional write to a coordination store. The file-append claim is good enough when collisions are rare and a human merges; don’t sell it as a lock.
Progress log — append-only, timestamped. An agent starting up reads the last day to orient itself: what got done, who’s working where.
Decision log — append-only; the spine that stops agent-B undoing agent-A’s reasoned choice. It’s load-bearing enough to get its own section, next.
The rules that keep this from unraveling:
- Branch per task; humans merge — prevents unreviewed changes hitting main; the merge is the human checkpoint.
- No agent-to-agent calls — prevents hidden side-channels; all coordination stays in the auditable files.
- Stable public surface (declared interface per module) — prevents parallel refactors breaking each other.
- Decisions are append-only and binding — prevents silent reversal of a load-bearing choice.
- Claim before touching shared or other-owned paths — prevents two agents editing the same file.
8. The decision log: ADRs for an AI build
Every non-trivial system accumulates decisions: we use this datastore, agents only propose, all model traffic goes through one gateway, this component may loop and the rest may not. Six weeks later nobody remembers why, someone “fixes” one of them, and a load-bearing choice quietly reverses. The classic remedy is the Architecture Decision Record. In an AI-assisted build — where agents make changes too — a decision log isn’t just hygiene, it’s the mechanism that keeps humans and agents from contradicting each other. A human team has hallway memory; agents don’t. An agent picking up a task reads the log to learn the constraints it must honor — and won’t reverse a choice whose reason it can’t see. (This is the DECISIONS.md from §3, grown up: once agents — not just you — make changes, it stops being a notebook and becomes an enforced contract.)
A single append-only file (or directory), each entry short and structured:
DEC-017 · 2026-06-10 · We route ALL model traffic through one gateway.
why: one place for rate-limits, cost tracking, the kill switch, and provider swaps.
alternatives rejected: per-service SDK calls (scatters cost + coupling everywhere).
status: accepted
The why and the rejected alternatives are the valuable part — they’re what stop the decision from being re-argued every quarter. Keep it as YAML if you want it machine-readable, so tooling can lint against it:
- id: DEC-017
  date: 2026-06-10
  decision: All model traffic goes through one gateway.
  why: single chokepoint for rate-limit, cost, kill switch, provider swap.
  rejected: [per-service SDK calls]
  governs: ["src/**"]        # which paths this decision constrains — makes the gate runnable
  forbids_imports: ["sdk-a", "sdk-b"]   # one machine-checkable rule (optional)
  supersedes: null           # status is DERIVED: an entry is "superseded" iff a LATER entry's `supersedes` points at it
Supersede, never edit
You never edit or delete a past decision; you change your mind with a new entry:
DEC-031 · 2026-07-02 · Supersedes DEC-017: the gateway also handles embeddings, not just chat.The history — reversals included — is itself valuable: it tells the story of how the system’s thinking evolved, and a half-remembered old entry is never silently wrong, it’s visibly superseded. Note status isn't a stored field you flip — it's derived from the supersedes pointers (an entry is superseded iff a later one points at it), so a past entry is never edited at all.
Make it binding, not passive docs
A log nobody enforces rots. Wire it into review so a diff that violates an accepted decision gets rejected:
governs is what makes this runnable — without it the gate can't know which decisions apply to a diff. forbids_imports is one cheap, fully machine-checkable violates() rule; richer checks need a human or an agent reviewer. Now the log isn't documentation that decays — it's an active constraint the build maintains. To change a decision, an agent writes a superseding entry and flags a human; it never silently codes around one.
What belongs in it
Put in the log: non-obvious, hard-to-reverse choices; architecture, data stores, security postures; the boundaries of agent autonomy; anything you'd be annoyed to see quietly undone.
Keep out: things the code already says plainly; transient implementation details; anything that changes freely without consequence; trivia (padding hides the important entries).
It pairs with the other append-only logs
A disciplined build ends up with a few records that rhyme — all append-only, dated, never rewritten: the decision log (why the system is built the way it is), the progress/coordination log (what got done and who’s working where — the file the parallel agents share above), and, if you’re building a system that makes decisions at runtime, an audit ledger (why it decided what it did in production). That shared discipline is what makes a fast build legible after the fact — to a new teammate, an auditor, an agent, or you in three months.
Anti-patterns
- Blaming the model — when quality slips, the reflex is “wait for the next model.” Far more often it’s a harness gap: a missing tool, a vague rule, a noisy context window. Fix the harness.
- No autonomy boundary — either you babysit every keystroke, or it pushes/deploys unreviewed.
- One mega context file — rots, and blows the budget on every turn.
- Context updated “later” — it’s never later; make staleness a same-diff bug.
- One self-review — one blind spot, applied uniformly; use a panel of lenses.
- A hook that silently rewrites docs — you lose the reviewable trail; emit a checklist, edit in the diff.
- Agents that message each other — hidden side-channels that don’t survive a restart; coordinate through shared files instead.
- No ownership map — two agents edit the same file and undo each other; default ownership by directory, claim to cross it.
- Editing a past decision instead of superseding it — you lose the history and make old copies silently wrong; append a superseding entry.
The takeaway
We’ve crossed from “AI writes a function” to “AI runs a project for weeks” — and then to “a fleet of agents runs it in parallel.” The bottleneck moved from can the model code to can the harness around it keep it honest, oriented, and reviewed over time. For one agent that harness is a constitution, an autonomy boundary, tiered context, durable memory, a review panel, and a post-edit hook. For several, add a shared written world to act on — an ownership map, a claim/release protocol, branch-per-task with human merges, and an append-only decision log wired into review so it’s binding.
None of this is specific to building AI systems — it’s how you run coding agents on any codebase. You don’t make the model reliable; you can’t. You contain the model and build the disciplined system around it. It’s cheap to set up and compounds every session — the difference between an intern who’s brilliant for an afternoon and an engineering team that gets better at your codebase every week.
I will package this as a drop-in kit later.
This is the build layer — the discipline applied to the agents that build the system. The five runtime layers underneath it (determinism, evaluation, confidence, safety, operability) are the rest of the series.
Series: Running LLM systems in production — Level 6 of 6: the disciplined build.