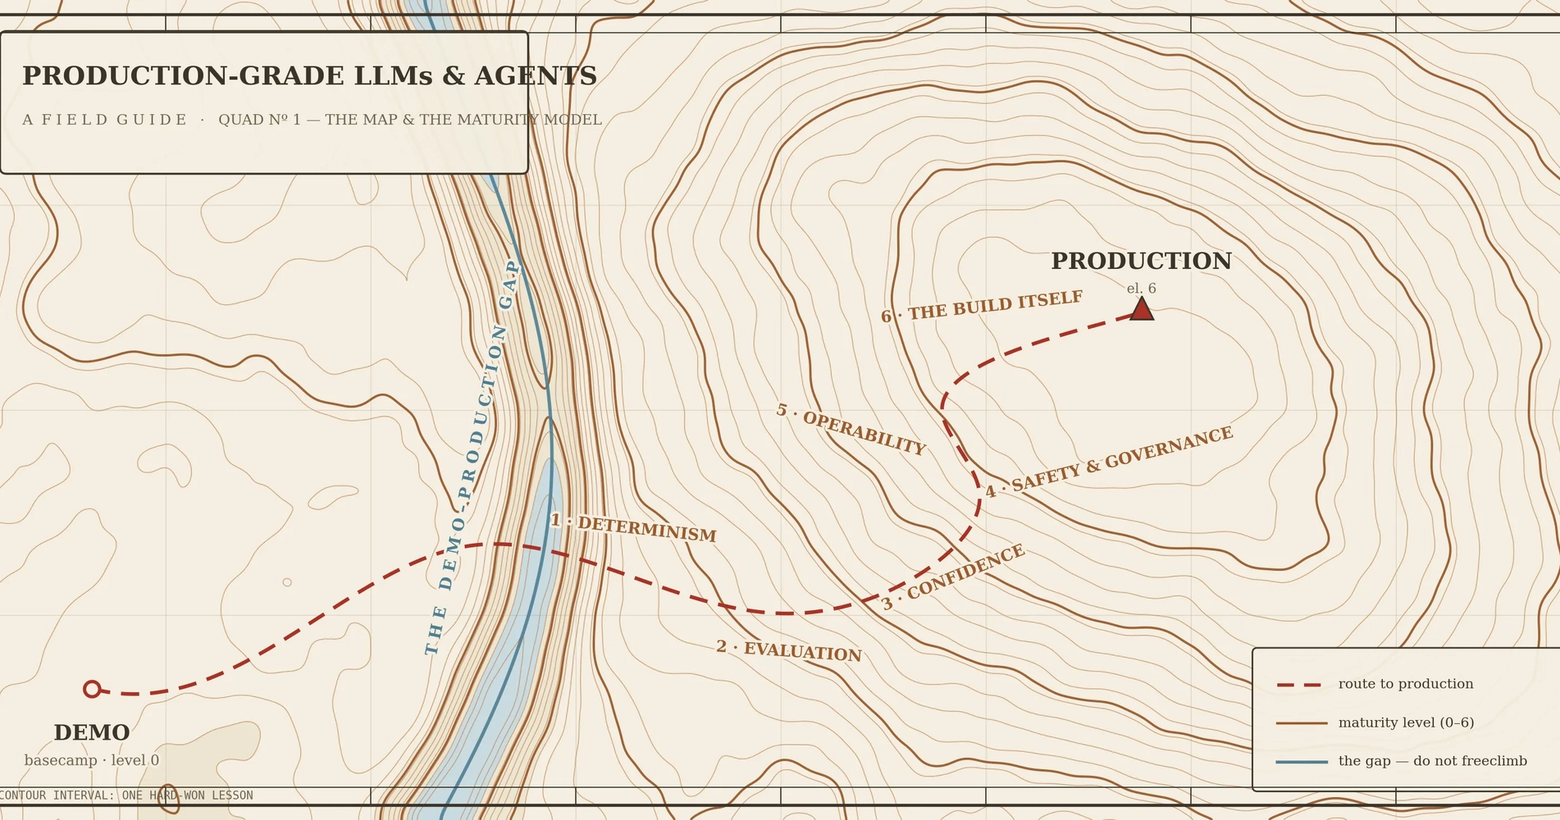
There’s a canyon between an agent that demos well and an agent you’d put in front of customers or money. Crossing it isn’t about a bigger model — it’s the boring machinery around the model: determinism, evaluation, calibrated confidence, layered guardrails, an audit trail, and observability. This post is the map and the maturity model. Each layer links to a focused deep-dive.
The one-paragraph thesis
LLMs are probabilistic; production demands guarantees. You get guarantees not by making the model deterministic (you can’t) but by shrinking the model’s job to the smallest decision that needs judgment, then wrapping that decision in deterministic machinery you can test, gate, audit, and observe. The model is one contained component in an otherwise ordinary, well-engineered system.
The maturity model
Levels you climb, each assuming the one below.
The level — What you have· The tell for gaps
- 0 - Notebook — a prompt, a model, a happy-path demo · “it works on my examples”
- 1 - Determinism— agents propose (never act); fixed graph per capability; model contained to one node; loops bounded · the agent can write business state; behavior depends on the path it wandered
- 2 - Evaluation — evals as a CI gate; baselines for drift; shadow evals from prod · you change a prompt and hope; evals live in a notebook
- 3 - Confidence — composed, calibrated confidence; auto-vs-human threshold; sampled judge · you act on raw model confidence; no abstention
- 4 - Safety & governance — defense-in-depth guardrails; PII at the boundary; append-only audit ledger; scoped memory · one moderation filter; raw inputs in logs; mutable audit
- 5 - Operability — observability of decisions; cost control; model routing + fallback; kill switch · you learn about quality/cost from the invoice and the customer
- 6 - Production-grade build — the build itself is disciplined — an OS for your coding agents, parallel agents on a decision log · tribal knowledge; decisions re-litigated every few weeks
How to use it: find your weakest level and fix that, in order. Most teams are strong at 0 and wish for 5 — but determinism comes before evals, evals before trusting confidence, confidence before automating, safety before scaling, observability before sleeping at night.
A 90-second self-assessment
Tick what’s true today:
- An agent can only propose; a separate component applies changes after approval.
- Each capability is a fixed sequence of steps; the model is one of them.
- A prompt/model change that regresses quality fails CI.
- You compare each release to a baseline, not just a pass/fail floor.
- Decisions carry a composed, calibrated confidence; low confidence routes to a human.
- Guardrails are layered (input, output, PII, verify, judge) and fail closed.
- Sensitive data is redacted/hashed at the boundary; the audit ledger is append-only.
- You can see decisions, guardrail blocks, token cost, and override rate on a dashboard.
- You can stop automated decisions in seconds without a deploy.
- Your hard-won decisions are written in a log humans and agents read.
Fewer than half ticked → you’re earlier than the demo suggests. The series below is the path.
The series — deep-dive per layer
Level 1 · Determinism 1. Make your AI agents boring · 2. Anatomy of an agent request · 3. Structured output over free-form · 4. Bounded ReAct: the one place loops belong
Level 2 · Evaluation 5. Evals as a deployment gate · 6. Drift detection in production
Level 3 · Confidence 7. Building on confidence · 8. LLM-as-judge · 9. Human-in-the-loop UX
Level 4 · Safety & governance 10. Defense-in-depth guardrails · 11. PII at the boundary · 12. The append-only audit ledger · 13. A memory model for multi-tenant agents · 14. Seed vs runtime
Level 5 · Operability 15. Hexagonal architecture for AI · 16. Observability for LLM systems · 17. Cost control · 18. Model routing & fallback · 19. Kill switches & graceful degradation · 20. Identity for agents · 21. What infrastructure an agent platform actually needs · 22. Making an agent pipeline fast
Level 6 · The build itself 23. Running a build with parallel autonomous agents · 24. The decision log 25. An operating system for coding agents
The takeaway
You don’t reach production by trusting the model more; you reach it by containing it more — and building the testable, measurable, auditable, observable system around it. Climb the levels in order. Each post below is one rung.
Series: Running LLM systems in production.
A maturity model for taking agents from an impressive demo to a system people can depend on — with a self-assessment and the map to a deep-dive on each layer.